AI’s Productivity Puzzle
Does AI improve productivity or create more work? Explore the evidence on gains, errors, rework, employee workloads and the wider economic payoff.

How gains and losses at work shape the wider economic payoff
§ Prologue
Apollo’s challenge
During the AI boom, one broad measure of U.S. business efficiency moved backward. Utilization-adjusted total factor productivity fell 0.34% over the four quarters through Q2 2026; unadjusted TFP rose 1.17%. TFP relates output to the combined labor and capital used. Both readings reflect many changes across the economy. Neither isolates AI’s contribution. [1]
Apollo economist Torsten Slok draws a provocative analogy: “Giving every employee a second monitor lifts output per hour without making the firm any smarter about how it operates.” He sees no AI dividend in the aggregate data. [2]
Workplace studies show gains and losses. AI changes tasks and the work left for people. Start with the task, follow the work through the organization, then ask how widely the result spreads and who benefits. Where does the time saved go?
Four independent readings
Different measures, different questions.
- Aggregate productivity−0.34%Utilization-adjusted TFP+1.17%Unadjusted TFP
U.S. business sector. Four quarters through Q2 2026.
Aggregate estimates combine influences from across the economy. Data [1]
- Customer support15% more issues resolved per hour
Support issues resolved per hour with an AI assistant. Study of 5,172 agents.
Main rollout: fall 2020–winter 2021. Researchers compared changes as access reached different groups of agents. Study [3]
- Experienced developers19% longer task-completion time
Measured task-completion time with early-2025 AI tools.
16 experienced developers; 246 tasks in familiar repositories. AI access was randomly assigned by task. Later tools and other settings require their own evaluation. Study [4]
- Retail search2.9% more spending per consumer
Spending per consumer when AI interpreted and translated search queries, compared with basic translation.
1.85 million consumers; three nine-day experiments on one platform, May–June 2024. Profit depends on sales margins and the full cost of providing the tool. Study [5]
Part I
What AI changes in the task
Start with work that reaches a customer. In a study of 5,172 support agents, access to an AI assistant increased issues resolved per hour by 15%. Less-experienced workers gained especially strongly, with evidence of learning; customers became less likely to ask for a manager. [3] The assistant helped staff apply knowledge while serving customers. More problems could be resolved with each hour of labor, inside the existing organization.
AI can also help people draw on knowledge outside their specialty. A Procter & Gamble experiment analyzed 791 professionals developing product ideas, individually or in pairs, with or without AI. The researchers described the quality of AI-assisted individuals’ ideas as comparable to that of pairs working without AI. Assistance also helped combine commercial and technical perspectives. [6] The experiment did not establish effects on everyday business performance or staffing.
Field experiment · Procter & Gamble
AI and the assembly of expertise.
Estimated differences in standardized solution quality, relative to an individual working without AI.
Reference: individual without AI. Zero represents the comparison group’s mean solution quality on the standardized scale.
- Pair without AI+0.245Reported SE 0.120
- Individual with AI+0.373Reported SE 0.106
- Pair with AI+0.392Reported SE 0.122
Difference in control-group standard deviations
Dots show estimated differences. Whiskers show ±1 reported robust standard error. The whiskers show uncertainty around each estimate.
View the reported estimates
| Condition | Estimated difference | Reported robust standard error |
|---|---|---|
| Individual without AI | 0 (reference) | Reference condition |
| Pair without AI | 0.245 | 0.120 |
| Individual with AI | 0.373 | 0.106 |
| Pair with AI | 0.392 | 0.122 |
Column 1 includes an intercept and treatment indicators. Quality is standardized using the control group. The reference is fixed at zero, and whiskers accompany the three estimated treatment effects. The intercept’s standard error is reported separately in the source.
A commercial employee could identify a technical difficulty before committing to a proposal. Specialists might join earlier, while changes are cheap, or concentrate on difficult cases. Smaller firms could access expertise they previously struggled to obtain. Reliable advice and the ability to use it matter. Better knowledge also raises a question about who has permission to act.
A retail experiment measured what customers bought. On one cross-border platform, AI interpreted and translated shoppers’ queries to improve search. Three nine-day experiments in May and June 2024 involved about 1.85 million consumers. Spending per consumer rose 2.9%. [5] Better matching offers a plausible explanation: shoppers can buy products they can find. Development, engineering and the costs of running the AI were incompletely measured. Profit and wider productivity require evidence beyond this short sales trial.
Office assistance can release time. A six-month experiment across 66 firms and 7,137 workers estimated about two fewer weekly email hours among tool users in months four to six. Activity outside regular hours also declined. Measured task volume and mix changed little; the meeting-time estimate was too uncertain to establish an overall change. [7] Released time could support other work or an earlier finish. Assistance can also make some work worse.
Where performance deteriorates
A BCG experiment shows how results can vary by task. Among 385 consultants working on 18 business subtasks, GPT-4 access increased the number completed by 12.2% and improved assessed quality. A separate group of 373 consultants recommended a business strategy using interviews and spreadsheet evidence. AI access reduced the probability of a correct answer by about 19 percentage points. [8] Each group had its own control. The decline concerned correctness on that selected assignment.
Field experiment · Boston Consulting Group
Performance depended on the task.
18 consulting subtasks
12.2% more subtasks completed
385 consultants assigned to this part of the experiment
Tasks assessed creative, analytical, writing and persuasive work within the tested system’s capabilities.
Strategic brand recommendation
About19 percentage points lower
Share reaching the correct recommendation
373 consultants assigned to this part of the experiment. The result combines both AI groups on a task outside the tested system’s capabilities.
The experiment used GPT-4 in 2023. The recommendation required combining evidence and avoiding a misleading answer. The authors suggest that consultants relied too heavily on AI advice. The experiment identifies the effect of access; it does not establish how much each behavior contributed to the mistakes. [8] Accepting fluent but incorrect advice can make the completed work less useful.
METR found an increase in work time. Sixteen experienced open-source developers completing 246 tasks in familiar codebases took 19% longer when allowed early-2025 AI tools, chiefly Cursor with Claude 3.5 or 3.7 Sonnet. Afterwards, they believed AI had cut completion time by about 20%. [4] Researchers observed developers reviewing and cleaning up AI output. This work suggests reasons for the slowdown, alongside the demands of familiar, complex codebases; their separate contributions remain uncertain.
METR’s February 2026 follow-up pointed toward faster work with newer tools, with uncertainty ranges that included no change. Selection of developers and tasks, and difficulties measuring work time, complicated interpretation. [9] The early result applies to a particular setting and tool generation. Both studies underline the need to measure completed work.
Learning can change too. In a randomized study of 52 developers using an unfamiliar programming library, AI assistance reduced scores on an immediate knowledge test; completion-time improvement was statistically uncertain. [10] This measures acquisition of new skills during one session. The support study described earlier found learning gains. An evaluation should ask what employees learn as well as what they finish. What do these results mean for the complete job?
Part II
What happens to the rest of the work
Consider a hypothetical proposal requiring one hour of drafting and nine further labor hours of preparation and review. AI halves drafting to thirty minutes, with quality and other work unchanged. Total labor falls from ten hours to nine and a half. A 50% drafting saving becomes a 5% reduction in the process’s labor input because drafting occupied one-tenth of the original work. That half-hour is available even if payroll and delivery time stay the same.
A hypothetical proposal · Labor hours
50% less drafting. 5% less labor.
Drafting falls from 1 hour to 30 minutes. Other labor stays at 9 hours.
30 minutesReleased capacity
0.5 ÷ 10 = 5%Labor-time saving
Delivery time is a separate outcome.A half-hour labor saving can coexist with an unchanged delivery time.
Now allow the rest of the work to change. Checking and correction can consume the thirty minutes or exceed them. Several AI-generated versions may improve the proposal, or add an unhelpful review burden. Software, computing, training and oversight also use resources. Count the full cost of a reliable completed proposal, including colleagues’ work. Better preparation could prevent expensive errors later, adding a benefit that the drafting timer misses. The result may be a smaller saving or a more costly process.
Work can move up the hierarchy
An analyst can save drafting time while creating work for a manager. If unchecked AI-generated analysis is passed upward, the manager may need to trace sources, test assumptions and reconstruct the argument, or return it for revision. Several such submissions could stretch review capacity and delay decisions. In a survey, U.S. desk workers reported evaluating, revising and sometimes redoing colleagues’ material they believed was AI-generated. [11] These reports cannot establish the net productivity effect. Count both people’s time, correction rounds and delivery. The test is whether the team completes more useful work overall.
Illustrative organizational mechanism
AI may move the bottleneck up the org chart.
Faster drafting can leave managers and specialists with more checking, correction and decisions.
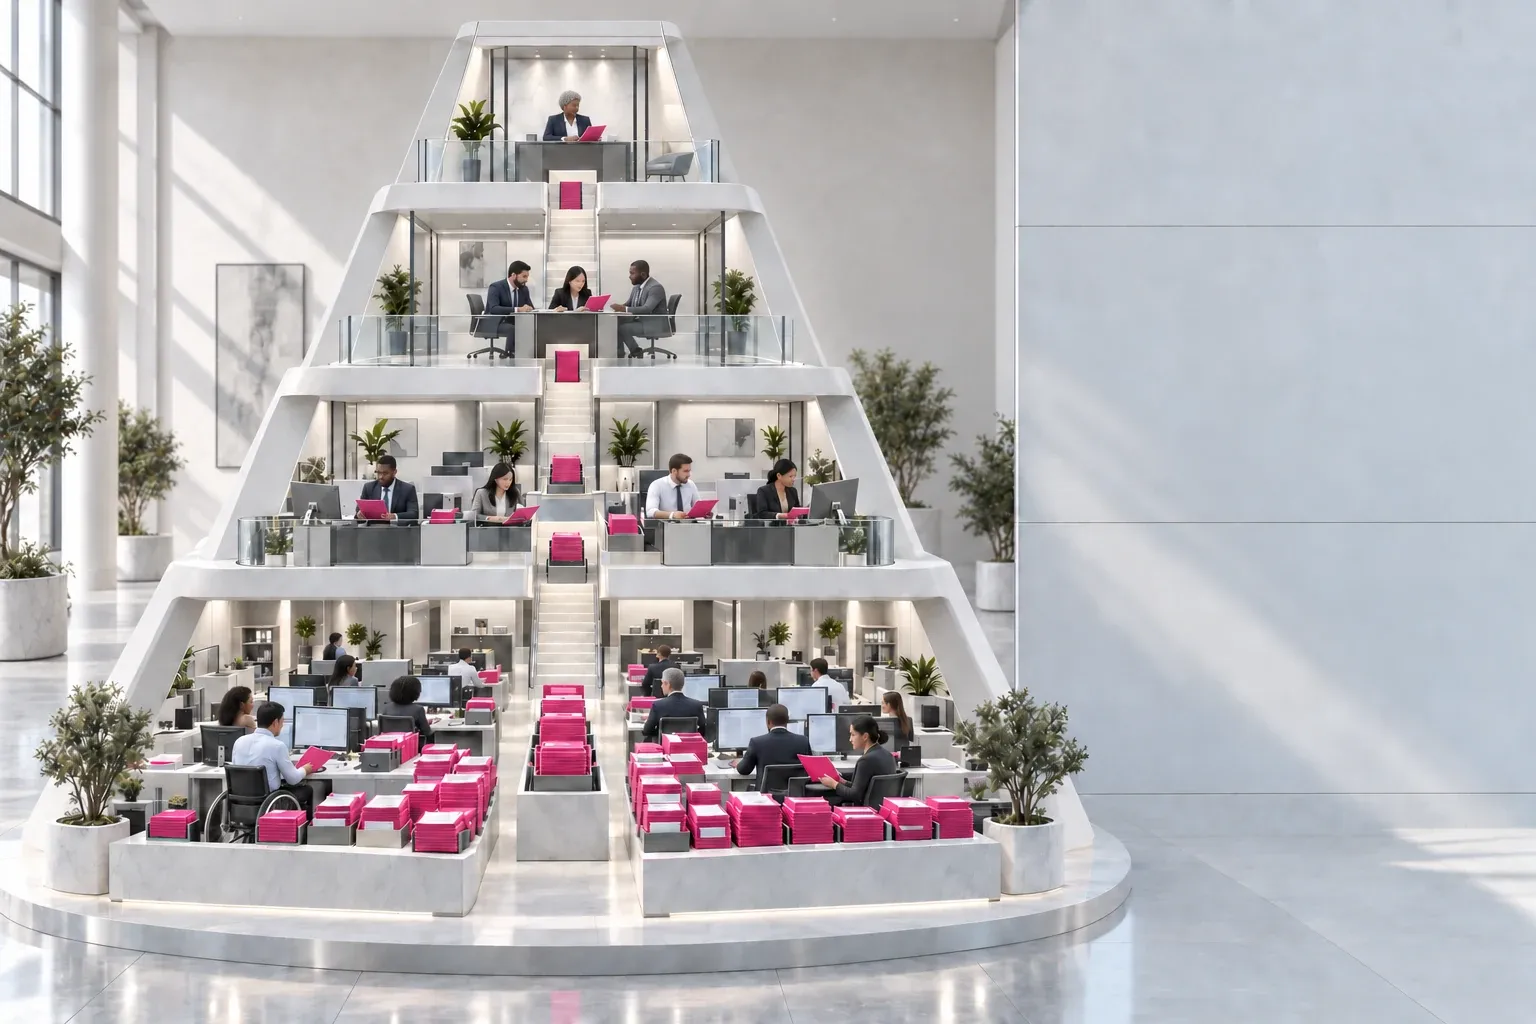
- AI-assisted draftsPrepared work enters the process.
- Checking and reworkColleagues check accuracy, fill gaps and correct errors.
- Decisions and approvalAuthorized people decide which commitments can proceed.
- Senior judgmentExceptions may reach senior staff for judgment.
Fuchsia folders represent prepared work awaiting review, correction or a decision.
Accountability remains with named owners at each stage.
The demands of the remaining work
Automation can also change the work left for people. In Cornell–McMaster research, contact-center workers described easier requests being automated while harder cases remained under unchanged time targets. Others reported losing breathing space between calls. Its 2022–23 US and Canadian surveys associated a wider range of automation and algorithmic tools with a larger share of time in customer contact, reported exhaustion and absence. The union-distributed surveys were self-selected; their comparisons cannot identify what caused the differences. They cover established tools, including routing and monitoring, without isolating today’s generative AI. [12]
The changing mix of calls also affects measurement. Once easy cases disappear, the average remaining call can take longer even if agents handle comparable cases just as well. Count successful automated resolutions and repeat contacts when assessing the complete service.
If demands outrun staffing, support and recovery opportunities, strain could increase costs. Absence or departures could leave colleagues covering gaps and training replacements, adding pressure. Cornell did not establish this full cycle: actual departures and replacement costs were unmeasured. Absence was not restricted to sickness. [12]
Different deployments can help employees. The support study described earlier associated AI assistance with lower attrition, although selective access could influence that result. [3] Follow workload and retention alongside speed to assess whether improvements last.
In the proposal example, total labor counts everyone’s working time. Delivery time measures how long the customer waits. Tasks can overlap; a completed draft can sit in an inbox. Saving thirty minutes might improve service immediately or leave the next scheduled review untouched. The employee could still use the time for another request, better preparation or an earlier finish. A late answer can cost the firm an opportunity. Following the proposal from request to delivery helps identify what is holding it up.
Responding to the actual constraint
Choose the response after diagnosing the delay. Unreliable submissions call for author checking and clearer standards. If review demand exceeds capacity, examine submission volume, quality, reviewer workload and correction rounds. Where records show sound proposals repeatedly waiting for routine pricing, technical or legal authorization, management could test a different route.
A named proposal owner could release cases within agreed pricing ranges, confirmed delivery capabilities and approved contract terms. AI would prepare evidence and flag mismatches; an authorized human would decide whether the conditions were met. Exceptions would go to the relevant specialist, then return to the owner for completion. Specialists would maintain the rules, check a sample of routine decisions and learn from recurring exceptions. A named person would remain accountable for each decision and its outcome.
This follows an older organizational idea: give people authority to complete routine work and reserve scarce expertise for harder problems. [13][14] Delegation predates AI and could help with existing tools. Better access to knowledge might support it. Easier oversight from the center could also draw decisions upward. Earlier studies linked information and communication technologies to differing patterns of authority inside firms. [15] AI’s effect needs examination in practice.
Rules need maintenance and dependable data. Managers may resist giving up approvals while remaining responsible for mistakes. Volume targets can encourage premature release. Employees rewarded for visible activity may hesitate to eliminate it. A trial needs clear authority, suitable incentives and oversight, while counting exception work and the specialist time needed to keep rules useful.
Compare completed orders, errors, quality, total cost and delivery time with the earlier route. A shorter approval wait would come from the changed process, separately from drafting savings. Evidence for this AI-supported arrangement remains insufficient. Across these settings, follow work transferred to colleagues or later periods. Then ask how widely the result spreads.
Hypothetical proposal · One route to test
Where approval holds up a routine case.
Existing approval route

Draft ready Scheduled review Customer
In this hypothetical case, routine approval holds up the completed proposal.
Release within agreed conditions

Owner checks Authorized release Customer
Human-approved rules cover routine cases. The accountable owner sends exceptions to the relevant specialist.
Test the change in practice. Follow delivery time, reliable output and the full resource cost, including rule maintenance and exceptions.
Part III
How those changes shape the wider payoff
A large gain in a narrow activity can have a small economic effect. Acemoglu’s model weights a task’s cost reduction by its share of production value. [16] Labor savings reduce only part of the cost; other inputs, quality, capital and new activities also matter. Actual use determines the reach. In May 2026, the Generative AI Adoption Tracker reported workplace use by 45.2% of employed respondents, while assisted work represented 6.3% of all working hours. [17] These self-reported measures count users and hours separately. We need evidence from different kinds of work: a customer-support gain cannot be applied to every assisted hour.
Census estimates for November 2025–January 2026 put recent AI use at about 18% of employer firms, representing roughly one-third of employment. Among firms using AI in a business function during the preceding six months, 57% named one to three functions; about 64% reported no changes to use AI during that period. [18] Breadth, intensity and recent adjustments measure different things. Deep changes can occur within few functions, and earlier changes may already yield benefits.
From task evidence to the wider economy
How far do workplace effects travel?
Net effect on a task
What changed in the work?
Measure time, quality and total cost, including the work needed to keep the process running.
Use in practice
How widely is that change used?
Who uses the tool, how often, and across which parts of the work.
Economic weight
How much activity does it affect?
How much of total production value comes from the tasks affected.
Account for investment and time. Training, better data, new tasks and changes in demand can shape the wider outcome.
Training, better data and new ways of organizing work require resources before benefits arrive. The productivity J-curve describes how investment in hard-to-measure capabilities can initially depress measured productivity. [19] Some investment, including software, is already counted in national accounts. [20] Useful capabilities may develop during the transition; projects can also fail. Spending needs evidence of useful results over time.
A randomized program involving 515 startups gave both groups the same AI access and core technical training. Extra workshops and peer learning explored where AI could fit production. At program week ten, firms offered that package were about 11 percentage points more likely to report paying customers. [21] The outcome was short-run and self-reported.
Firm surveys add reports of wider benefits. Federal Reserve and Duke research involving nearly 750 executives inferred AI-related gains in revenue per employee from firms’ reports. These estimated gains were associated with aims to innovate and reach customers. PwC found that firms reporting leading AI financial results were about twice as likely to report changing workflows. [22][23] These associations leave room for demand, prices, management and resources to explain differences. Revenue gains require separate cost evidence.
That brings us back to Apollo. AI could contribute positively while other changes pull adjusted TFP down. The evidence here does not estimate its contribution to that reading. Business-sector output per hour grew about 2.5% annually from Q1 2023 to Q2 2026, against 1.5% during 2005–2022. [24] This different measure and period also capture many developments. Better equipment can embody innovation; new services can create value. Establishing AI’s contribution requires credible comparisons, evidence about use and economic importance, and time for costs and benefits to emerge. Who receives any gain is a further question.
Who receives the benefit?
Customers may receive quicker answers, better products or more reliable service. Competition can pass cost savings into lower prices, leaving suppliers’ margins little changed. Stronger demand can turn available capacity into additional sales. A small contract may become worth preparing, or a small business may offer a service it previously could not afford. The remaining work still needs enough capacity. A firm with a waiting list has different options from one struggling to find its next buyer.
Workers’ outcomes need their own evidence. A Danish study linked surveys in eleven exposed occupations to administrative records through December 2024. It found little average effect of chatbot adoption on earnings or recorded hours. Its pooled comparisons of adopters’ and non-adopters’ average outcomes ruled out effects larger than 2% within that window. [25] Tasks can change while these measures stay stable. Firm output and later labor-market effects would require other evidence.
Adopters reported saving roughly 3% of their work hours. Among users reporting any savings, about 85% expected to spend more time on other tasks. [25] The 85% describes respondents’ intended use of saved time; the 3% estimates the hours saved. Someone could finish correspondence sooner and take on another assignment, keeping the same salary and scheduled day. Earnings and hours records would capture only part of that change.
The employee could gain time, a lighter workload or higher pay. Employers could raise targets, reduce hiring or cut positions. Weak demand may push employers to reduce staffing costs; expanding demand may support more output with existing staff. The studies leave open how often each response occurs. Bargaining power, employment arrangements and managerial choices help determine who keeps the benefit. Retaining saved time requires a workload and schedule that allow it. The demands of remaining tasks and opportunities to recover matter too.
Distribution of the benefit
Who receives the gain?
The customer
A more useful answer, better service or a lower price.
Competition helps determine how much reaches buyers.
The business
Capacity to serve more customers or pursue another opportunity.
Additional sales depend on demand and remaining capacity.
The employee
A lighter workload, an earlier finish or higher pay may follow. The work that remains can also become more demanding.
Targets, bargaining and working arrangements shape what is retained.
Productivity and job security can move differently. A more efficient operation may offer better work and more accessible services, or employ fewer people. Higher profits can accompany a heavier workload. Strain deserves attention even where output keeps rising. A full assessment follows customer outcomes, business costs and employees’ experience, including changes that pay and hours records cannot show.
§ Conclusion
What the evidence supports
AI has produced measurable gains in service throughput, solution quality and short-run retail sales. Particular deployments have also reduced correctness and lengthened completion time. Their wider consequences depend on the complete job: work removed, work created and the demands of what remains.
The business account must include checking, correction and the resources needed to sustain a reliable service. Delivery has its own timetable. Employee learning, workload and retention deserve attention alongside immediate output. A saving today may be strengthened or diminished by what happens later.
Estimating the economy-wide effect requires knowing how widely and intensively AI is used, the value of affected work and how costs and benefits develop. Apollo’s challenge remains useful. These workplace findings do not establish why adjusted TFP fell or quantify AI’s contribution.
Follow completed output, quality, full cost and delivery time, then examine pay, workload and employment. Compare results over time with credible alternatives. Where did the saved time go, what useful result lasted, and who benefited?
Source notes
Sources are numbered by first appearance across the article and figures. Publication dates and study settings are identified below.
[1] Federal Reserve Bank of San Francisco. Total Factor Productivity. Dataset and summary, updated September 3, 2026.
Quarterly estimates for the U.S. business sector. TFP relates output to the combined labor and capital used to produce it. Both headline readings cover the four quarters through Q2 2026. The utilization adjustment accounts for how intensively labor and capital are used. Many changes across the economy affect these estimates, which remain subject to revision. Establishing AI’s contribution requires a separate study designed to identify its effect. The quarterly utilization-adjusted series also retains influences such as reallocation and imperfect competition. These methodological limits do not identify the cause of the reported decline.
Primary source · Current paper
Return to: Apollo’s challenge · paragraph 1 · Figure 1
[2] Torsten Slok. No Signs of AI in the Productivity Data. Apollo, The Daily Spark, October 5, 2026.
The dated entry supplies the second-monitor quotation and interprets aggregate TFP as showing no AI payoff. This is an interpretation of growth-accounting data, without a separate causal estimate of AI’s contribution. The article’s proposal and approval route are hypothetical. The contact-center survey supplies a different, descriptive workplace example. Neither explains Apollo’s aggregate observation.
Return to: Apollo’s challenge · paragraph 2
[3] Brynjolfsson, Li and Raymond. Generative AI at Work. The Quarterly Journal of Economics 140(2), 2025, pp. 889–942.
The main assistant rollout ran from fall 2020 to winter 2021 and involved 5,172 customer-support agents. The 15% estimate concerns resolved issues per hour. The researchers used a difference-in-differences design around staggered access; an earlier small pilot was randomized. The manager-related outcome records customers asking to speak to a manager. Section VII.C associates AI access with lower attrition, especially among newer agents. Attrition combines voluntary and involuntary departures. Its once-per-worker occurrence prevents worker fixed effects in that analysis, and selective access for people likely to stay could overstate the association. These results do not establish that assistance reduced exhaustion or the costs of replacing staff.
Primary source · Open article PDF · Open author version
Return to: Figure 1 · What AI changes in the task · paragraph 1 · What happens to the rest of the work · paragraph 7
[4] METR. Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity. July 10, 2025.
Access to early-2025 tools was randomized by task for 16 experienced developers completing 246 issues in familiar repositories. Measured completion took 19% longer; participants later estimated that AI had saved about 20% of their time. For fixed output, productivity is proportional to one divided by completion time. The result concerns these tools, tasks and experienced participants. Newer tools and other working conditions need their own evaluation. The current paper inspected is arXiv 2507.09089v2, July 25, 2025. Observations of checking and cleanup suggest possible reasons for the slowdown. Their individual causal contributions remain uncertain.
Primary source · Current paper
Return to: Figure 1 · What AI changes in the task · paragraph 8
[5] Fang, Yuan, Zhang, Donati and Sarvary. Generative AI and Sales Productivity: Field Experiments in Online Retail. arXiv 2510.12049v6, submitted June 29, 2026; manuscript dated June 30.
The search treatment used AI to translate and refine queries, compared with basic translation. Three nine-day experiments in May–June 2024 randomized 1,849,382 consumers on one cross-border platform. Table 4 reports a 2.9% spending increase; Appendix Table C3 gives the underlying estimate. Full development, engineering and inference costs were unavailable. Inference means running the model to produce responses. Assessing profit, market expansion, sales displaced from competitors and longer-run productivity requires further evidence. This revision replaces the earlier paper’s broader productivity framing.
Return to: Figure 1 · What AI changes in the task · paragraph 4
[6] Dell’Acqua and coauthors. The Cybernetic Teammate: A Field Experiment on Generative AI and Teamwork. Organization Science 37(4), 2026, pp. 1217–1242.
Structured P&G product-innovation exercise analyzing 791 professionals. The analysis excludes 35 late or senior attendees whose assignment was nonrandom. The paper describes randomized assignment and additional reassignments from incomplete teams. Figure 2 uses Table 2, column 1: 550 solution-level observations in a regression containing an intercept and treatment indicators. Points show standardized quality differences from individuals working without AI. Each whisker extends one reported robust standard error on either side. Confidence intervals require a specified confidence level and the corresponding critical value. Establishing equivalence between conditions requires a dedicated test. Staffing, everyday operations and delegated authority need further evidence.
Primary source · Open article PDF
Return to: What AI changes in the task · paragraph 2 · Figure 2
[7] Dillon, Jaffe, Immorlica and Stanton. Shifting Work Patterns with Generative AI. Revised working paper, arXiv version 4.
Six-month randomized access experiment covering 7,137 workers at 66 firms. The approximately two-hour weekly email saving is the estimated effect among tool users in months 4–6. The estimate for being assigned access is about 1.4 hours. Measurement covers activity in the Microsoft applications observed, including Teams meetings. Work quality, profit and performance need additional outcome data. A statistically insignificant estimate leaves uncertainty about the true effect. The version’s displayed header and manuscript body give different dates; the linked version identifies the text used here.
Return to: What AI changes in the task · paragraph 5
[8] Dell’Acqua and coauthors. Navigating the Jagged Technological Frontier. Organization Science 37(2), 2026, pp. 403–423; online March 11, 2026.
Preregistered randomized study of 758 BCG consultants using GPT-4 in 2023. The two task groups involved 385 and 373 consultants. Tables 5–6 report 12.2% more completed subtasks and 25.1% less time to reach question 18. In Table 7, the control group’s correct-answer rate is 0.844; the two treatment coefficients are −0.139 and −0.245. The paper’s text and tables establish an approximate combined decline of 19 percentage points. The abstract describes that decline imprecisely as a percentage. Randomized access identifies effects on these assignments. Overreliance on AI is the authors’ interpretation of why correctness fell.
Primary source · Open article PDF
Return to: What AI changes in the task · paragraph 6 · Figure 3 · What AI changes in the task · paragraph 7
[9] METR. We are Changing our Developer Productivity Experiment Design. February 24, 2026.
The follow-up’s estimates pointed toward faster work, with uncertainty ranges that included zero effect. Problems involved participant and task selection, changed incentives and the measurement of work with several AI agents running at once. These issues weaken comparisons with the earlier trial and conclusions about how newer tools changed performance. A separate May 2026 convenience survey asked a selected sample about perceived value gains. Establishing a causal reversal of the original result would require evidence designed to compare performance under the relevant conditions.
Return to: What AI changes in the task · paragraph 9
[10] Judy Hanwen Shen and Alex Tamkin. How AI Impacts Skill Formation. arXiv:2601.20245v2, 2026; preprint.
Preregistered randomized study with 52 analyzed participants, 26 per group, learning the unfamiliar Python Trio library. Participants had Python experience; most were professional or freelance developers. GPT-4o assistance reduced the immediate knowledge-test score by 4.15 points on a 27-point test. The main study did not establish a statistically significant completion-time improvement. Sections 4–5 and Figure 6 define the experiment and result. The test assesses newly acquired knowledge during that session. Longer-term changes in existing expertise remain unmeasured. The source’s percentage conversion is not used here. arXiv records version 2 on February 1, 2026; the PDF displays February 3 and the HTML August 24. The version identifier fixes the text inspected despite these date differences.
Primary source · Open article PDF
Return to: What AI changes in the task · paragraph 10
[11] Alex Liebscher, Angela Y. Lee, Kristina Rapuano, Gabriella Kellerman, Kate G. Niederhoffer and Jeffrey T. Hancock. Workslop: Examining the Prevalence, Antecedents and Consequences of Low-Quality AI-Generated Content at Work. PsyArXiv preprint, version 1, February 5, 2026.
Cross-sectional online survey fielded in September 2025 through CloudResearch Connect. The final sample contains 962 US full-time desk workers from 1,015 recruits: 11 failed attention checks and 42 were excluded after manual review of responses. Respondents described evaluating, discussing, revising and sometimes redoing colleagues’ work they believed was AI-generated. Pages 5 and 7 describe recruitment and questions; pp. 13–14 report recipient experiences. Managers reported greater cognitive effort in the adjusted analysis; higher managerial hours and predominantly upward movement remain unestablished. The data rely on recalled experiences and subjective quality judgments. Independent confirmation of AI authorship and measured time logs was unavailable. Pages 17–18 discuss these limits and the cross-sectional design. The analyst-to-manager example in this article is a conditional application; its frequency and net effect require workplace evidence. The manuscript is a preprint awaiting peer review. BetterUp funded data collection; the authors disclose employee and consulting relationships on p. 19. This article uses the qualitative recipient finding and avoids the source’s inconsistent numerical summaries.
Primary source · Open article PDF
Return to: What happens to the rest of the work · paragraph 3
[12] Virginia Doellgast, Sean O’Brady, Jeonghun Kim and Della Walters. AI in Contact Centers: Artificial Intelligence and Algorithmic Management in Frontline Service Workplaces. Cornell ILR / McMaster report, 2023.
Qualitative cases cover four countries; the union-distributed surveys include 2,891 US and 385 Canadian respondents, with smaller samples for individual outcomes. Appendix 1 dates US fieldwork to December 2022–January 2023 and Canada to late January–early March 2023; the introduction compresses both into the earlier window. Table 1, pp. 19–20, contains worker accounts of harder remaining cases and unchanged time targets. Figures 18–19 and 49–54 report associations involving customer-contact time, emotional exhaustion, absence and intentions to seek another job. The eight tool categories include established automation, routing, scheduling and monitoring. The count records how many tool categories each respondent reports. Hours of AI use and operational utilization remain unmeasured. Closed-key time includes work without customer contact; it is broader than recovery time. Absence excludes vacations but is not limited to sickness. Actual departures and replacement costs were unmeasured; differences in intentions to leave were small. The overall exhaustion-scale association was statistically significant in the US and uncertain in Canada. Self-selection and other differences between workplaces prevent a causal interpretation of these comparisons.
Primary source · Open article PDF
Return to: What happens to the rest of the work · paragraph 4 · What happens to the rest of the work · paragraph 6
[13] Luis Garicano. Hierarchies and the Organization of Knowledge in Production. Journal of Political Economy 108(5), 2000, pp. 874–904.
A theoretical model of specialized knowledge in which communicating a problem takes resources. People doing production work handle common or easier problems; harder problems go to specialist problem solvers. This helps explain why organizations refer cases to experts. The model sets incentives aside. Applying it to AI requires evidence about the tasks, staffing and organizational arrangements involved.
Primary source · Open article PDF
Return to: What happens to the rest of the work · paragraph 11
[14] Philippe Aghion and Jean Tirole. Formal and Real Authority in Organizations. Journal of Political Economy 105(1), 1997, pp. 1–29.
Theory distinguishing the formal right to decide from effective control over a decision. Delegation can encourage initiative while reducing a superior’s control. This distinction helps explain how access to knowledge and permission to act shape organizational choices. The operating rules and exception process illustrated here would need evaluation in practice, including their oversight arrangements.
Return to: What happens to the rest of the work · paragraph 11
[15] Bloom, Garicano, Sadun and Van Reenen. The Distinct Effects of Information Technology and Communication Technology on Firm Organization. Management Science 60(12), 2014, pp. 2859–2885.
Theory and manufacturing-firm evidence from the United States and Europe. ERP and CAD/CAM information systems were associated with greater local autonomy. Intranet communication was associated with less. These are earlier technologies; applying their distinction to AI is an inference. AI’s effects on delegation, staffing and management layers require empirical evidence.
Return to: What happens to the rest of the work · paragraph 11
[16] Daron Acemoglu. The Simple Macroeconomics of AI. Economic Policy 40(121), 2025, pp. 13–58.
Equations 12–14 link task-cost reductions to aggregate productivity under the model’s assumptions about production and markets. Each task is weighted by its GDP share, based on the value it produces. Converting labor-cost savings into total task-cost savings also requires labor’s share of that task’s costs. Changes in capital per worker, quality and new tasks need their own treatment when extending this approximation. The MIT copy is the typeset advance article downloaded from OUP on October 4, 2024.
Primary source · Open article PDF
Return to: How those changes shape the wider payoff · paragraph 1 · Figure 7
[17] Bick, Blandin, Deming and the Real-Time Population Survey team. Generative AI Adoption Tracker. May 2026 survey; FRED series updated August 4, 2026.
Weighted U.S. survey of employed adults aged 18–64 for these work measures. Reported workplace use is 45.2% of respondents. Estimated assisted hours are 6.3% of all working hours. That estimate is the midpoint of lower and upper bounds calculated from response ranges. Users and hours have different denominators; both measures rely on self-reports. Work use in the previous week is a separate 39.2% measure. The series are RPSGENAIUSAGESHAREWORK and RPSGENAIASSISTWRKHRSALL. The published adoption paper uses earlier data. Measuring the resulting changes in output and costs requires additional evidence.
Primary source · Data and definitions
Return to: How those changes shape the wider payoff · paragraph 1 · Figure 7
[18] Bonney and coauthors. The Microstructure of AI Diffusion: Evidence from Firms, Business Functions, and Worker Tasks. U.S. Census Bureau, CES-26-25, April 2026.
The population is private non-agricultural employer firms, with a November 2025–January 2026 reference period. Q23 asks about use in the previous two weeks: 17.9% of firms reported use, representing 31.2% of employment. Q24 covers business-function use over six months: 57% of those users name one to three functions. Q29 asks these business-function users about changes made to use AI during the preceding six months; about 64%, on the firm-weighted measure, reported none. Each question has its own population and time window. The survey defines AI broadly. Business gains and earlier organizational changes need separate evidence.
Return to: How those changes shape the wider payoff · paragraph 2
[19] Brynjolfsson, Rock and Syverson. The Productivity J-Curve: How Intangibles Complement General Purpose Technologies. American Economic Journal: Macroeconomics 13(1), 2021, pp. 333–372.
A model and historical analysis of investment in intangible assets that help a technology work. Poorly measured investment can initially depress measured productivity growth, with benefits appearing later. A particular project’s success depends on whether it builds useful capabilities and on the value they eventually produce.
Return to: How those changes shape the wider payoff · paragraph 3
[20] Tina Highfill, David B. Wasshausen and Gregory Prunchak. Concepts and Challenges of Measuring Production of Artificial Intelligence in the U.S. Economy. BEA Working Paper 2025-1, January 2025.
Section 2, particularly printed pp. 3–6, explains how AI-related software and research and development already enter the national accounts, including capital expenditure. Software need not be separately labeled as AI to be counted. The illustrative accounting examples do not estimate adoption’s wider productivity effects. This supports distinguishing gaps in the measurement of some complementary capabilities from an assertion that all AI investment is omitted.
Return to: How those changes shape the wider payoff · paragraph 3
[21] Hyunjin Kim, Dahyeon Kim and Rembrand Koning. Mapping AI into Production: A Field Experiment on Firm Performance. INSEAD Working Paper 2026/20/STR, March 30, 2026.
Randomized learning program across 515 startups. Workshops on applying AI and peer learning were compared with the accelerator’s control curriculum; both groups had the same AI access and core technical training. Treatment ran September 8–October 26, 2025, ending at program week ten. Table 4, column 3 estimates an 11-percentage-point increase in reporting paying customers. The control mean was 62.6%; 479 firms supplied endline data. The outcome is short-run and self-reported. The assigned treatment was a package of learning activities. Testing changes in approval rights, full realized resource costs or long-run survival would require further evidence.
Primary source · Open article PDF
Return to: How those changes shape the wider payoff · paragraph 4
[22] Baslandze and coauthors. Artificial Intelligence, Productivity, and the Workforce: Evidence from Corporate Executives. Federal Reserve Bank of Atlanta, Working Paper 2026-4, March 25, 2026.
Federal Reserve and Duke survey: 603 core and 145 supplemental responses, collected November 2025–January 2026. The researchers infer AI-related changes in revenue per employee from firms’ own reports. Measures based on revenue can reflect demand, prices and markups as well as physical efficiency. Aggregate value-added TFP uses a different accounting framework. The sample’s representativeness and the conclusions about causation are limited. Answers about 2026 outcomes express executives’ expectations.
Return to: How those changes shape the wider payoff · paragraph 5
[23] PwC. 2026 AI Performance Study, official results release, April 13, 2026.
Survey of 1,217 senior executives across 25 sectors, primarily at large listed firms. The approximate twofold comparison links reported leading AI financial results with reported workflow changes. Management, resources and other firm characteristics may help explain the relationship. Establishing the effects of this article’s delegation example would require a comparison of that process and its outcomes.
Return to: How those changes shape the wider payoff · paragraph 5
[24] Huiyu Li. SF FedViews: Productivity-Driven Growth Confronts Elevated Inflation. Federal Reserve Bank of San Francisco, September 3, 2026.
Business-sector output per hour grew at an average annualized 2.5% from Q1 2023 to Q2 2026, compared with 1.5% during 2005–2022. This measures a different outcome over a different period from the opening’s TFP comparison. Capital investment, the intensity of input use and other changes contribute to the aggregate readings. Estimating AI’s effect requires evidence that separates these influences.
Return to: How those changes shape the wider payoff · paragraph 6
[25] Anders Humlum and Emilie Vestergaard. Still Waters, Rapid Currents: Early Labor Market Transformation under Generative AI. Author manuscript, March 13, 2026.
Surveys in eleven exposed occupations are linked to Danish administrative records through December 2024. The pooled difference-in-differences estimates for earnings and recorded hours rule out effects larger than 2%; the dynamic estimates have different bounds. Table E.3 estimates savings averaging roughly 3% of adopters’ hours. Among adopters reporting savings, 84.7% expected to spend more time on other tasks. This counts respondents answering a question about intended use. The hours calculation uses the midpoints of response categories and an eight-hour workday. Firm output and later employment effects would require other estimates.
Return to: How those changes shape the wider payoff · paragraph 8 · How those changes shape the wider payoff · paragraph 9